XML Sitemap Best Practices: Limits, Index Files and Dead URLs
Audit sitemap URLs, respect size limits and read lastmod correctly. Learn why Google ignores priority and changefreq, and why HTTP 200 is only one check.
Like it ? share it
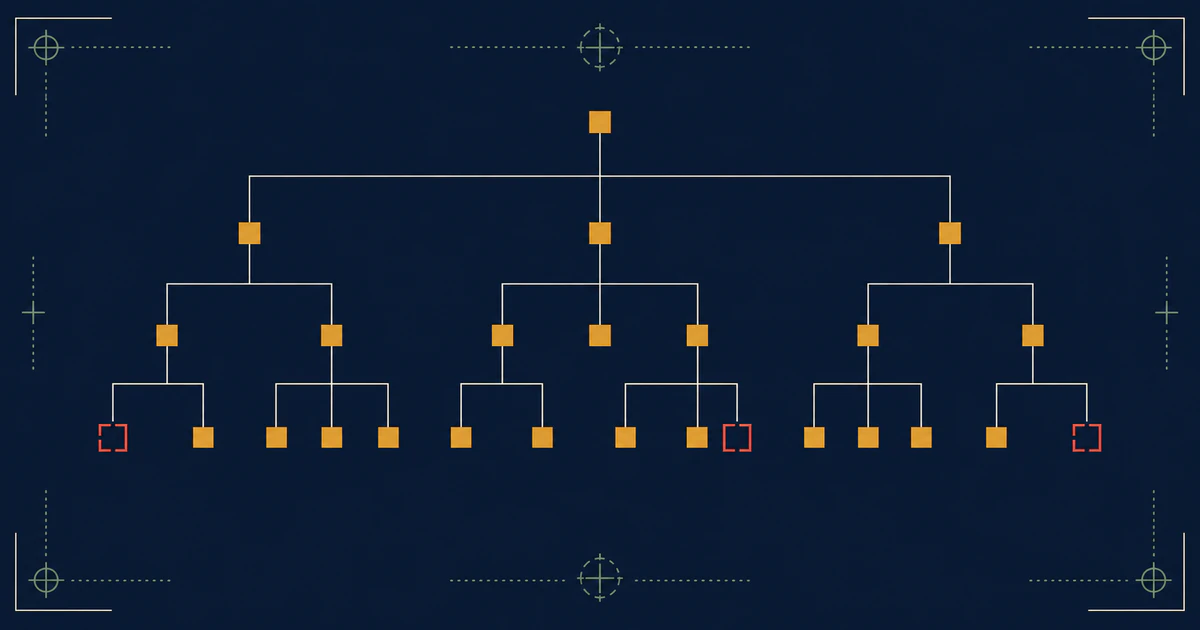
A small site may need only one sitemap.xml. As the URL list grows, two limits matter: 50,000 URLs per sitemap and 50MB per file before compression. If you exceed either limit, split the list into multiple sitemaps. A sitemap index can point to those files.
A valid XML file is only the first check. The URLs inside it should be the canonical pages you want search engines to discover, rather than old redirects, missing pages or pages carrying noindex.
What a sitemap index contains
A standard sitemap lists pages. A sitemap index lists sitemap files. A structure might separate content by type:
sitemap_index.xml
  post-sitemap.xml       blog posts
  page-sitemap.xml       static pages
  product-sitemap.xml    product pages
Separating the files can make troubleshooting easier. If product discovery drops, you can inspect the product sitemap directly. Each child sitemap still needs to satisfy the URL and uncompressed-size limits. Gzip compression can reduce transfer size, but it does not raise those limits.
Google's sitemap guidance covers these requirements. Submission helps discovery; it does not guarantee crawling or indexing.
Extract the URLs before checking them
Open the Sitemap URL Extractor and enter the sitemap or index address. A standard sitemap returns page URLs. An index returns the addresses of its child sitemap files, so check the reported file type before treating the result as a page list.
For an index, open each child sitemap in the extractor, export its page URLs, and combine the URL columns for the audit. The current tool does not automatically flatten the index into all of its child pages. If a downloaded .xml.gz file does not parse, decompress it first or use an available uncompressed XML version.
Review the extracted URLs and metadata, then export CSV. The extractor offers an optional status check, but on an index that checks the listed sitemap files. Extract the child pages before checking page responses. For a separate pass over a URL column, use the Bulk URL Checker; the Excel-to-CSV guide shows a complete run.
Keep file extraction and URL checking separate in your interpretation. Successfully parsing a sitemap does not establish that every listed page works. Checking HTTP responses does not establish that Google indexed the pages.
Check lastmod and canonical URLs
lastmod should reflect the last significant change to the page. A date from two years ago on a page you rewrote last month can reveal a generator that misses updates. Setting every page to today's date whenever the sitemap regenerates can be misleading too.
For Google, <priority> and <changefreq> are ignored. You may see those columns in an extracted file, but adjusting them is not a Google ranking or crawl-frequency control. Focus on accurate lastmod values and the actual pages being listed. Google documents these metadata rules here.
Use complete absolute URLs with the intended scheme and host. Prefer each page's canonical address rather than including every parameter variant or an old address that redirects to it.
Interpret the responses
| Finding | Meaning | Action |
|---|---|---|
Final response 200 |
The request succeeded | Check content, canonical and indexing directives where relevant |
404 or 410 |
The resource is not found or is gone | Remove an obsolete entry; check for a wrong address before deleting a valid page |
| A redirect found with a redirect check | The listed address leads elsewhere | Use the intended canonical destination in the sitemap |
403 or 429 |
Access was refused or rate limited | Review access controls or retry before treating the URL as missing |
5xx or timeout |
The request failed | Investigate server availability and retry |
Both the bulk checker and the extractor's status check follow redirects. A redirect ending at a working page may therefore show 200, hiding the initial 301 or 302 from that results table. Use the Redirect Detector when you need the hops and destination, then compare that destination with the expected canonical page.
HTTP 200 needs another check when indexing is the concern. A page can return a successful status while showing an error message, pointing its canonical elsewhere or carrying noindex. Use Search Console URL Inspection for pages you own; its indexing report answers a different question from a URL status check.
Check durations depend on list size and target servers. A short healthy list may finish quickly, while slow responses, retries and rate limits can stretch a run. Keep the tab open during a check and wait for completion before exporting the final results.
Fix the source and submit the file
When a generated sitemap contains deleted pages, fix the generator or its source data so the entries do not return on the next build. If an old URL has a relevant replacement, a redirect may still help visitors and existing links; the sitemap should list the replacement's canonical address.
Keep intentionally non-indexable pages out of the sitemap. If a useful page was accidentally marked noindex, fix that directive rather than silently deleting it from the list. For crawl restrictions, compare the URL with robots.txt as a separate step.
You can submit a sitemap index in Search Console and let Google discover its children. Google also allows multiple sitemap or index submissions; separate submissions can help you track sections individually. Choose the arrangement that helps you monitor the site, rather than submitting duplicates to increase coverage.
Recheck after migrations, changes to canonical URLs, large deletions and sitemap-generator updates. Save the exported results so the next audit can distinguish new failures from ones already being investigated.